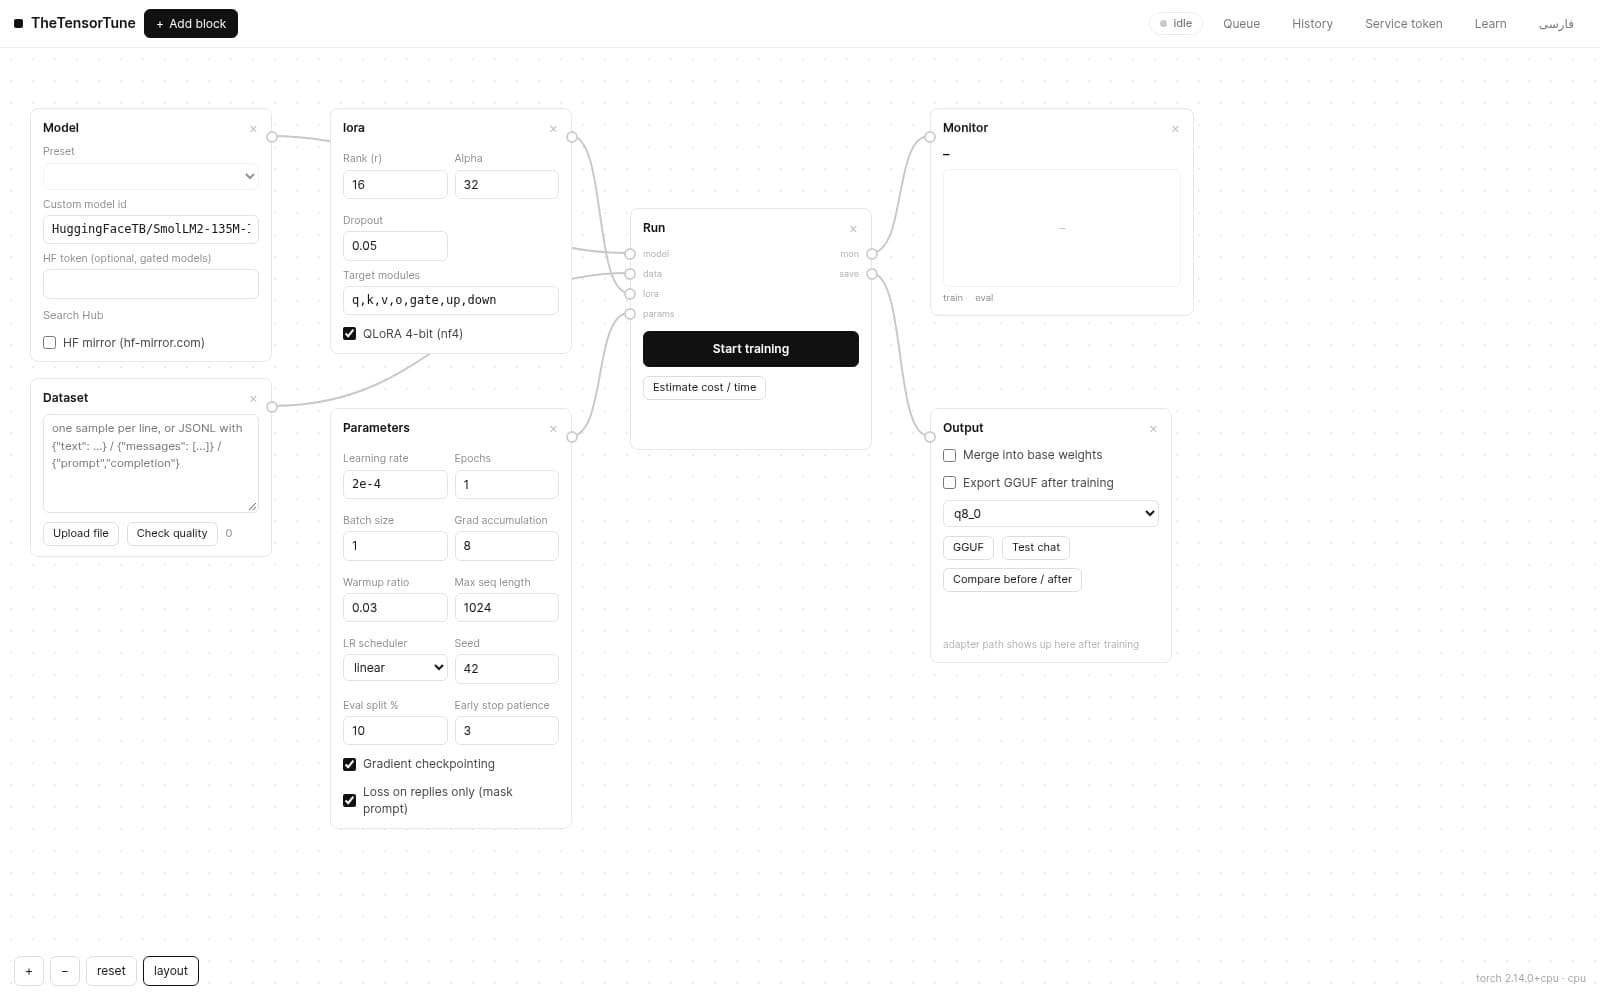
The compare button (on the Train block or in History) puts the base model and the tuned model side by side:
- Perplexity (ppl): language-model error — lower is more confident. A drop like ~29 → ~3 means the dataset style was genuinely learned.
- eval loss: measured on the held-out split (when eval_pct>0).
- sample generation: the same prompt goes to both models so you can see the behavioural diff.
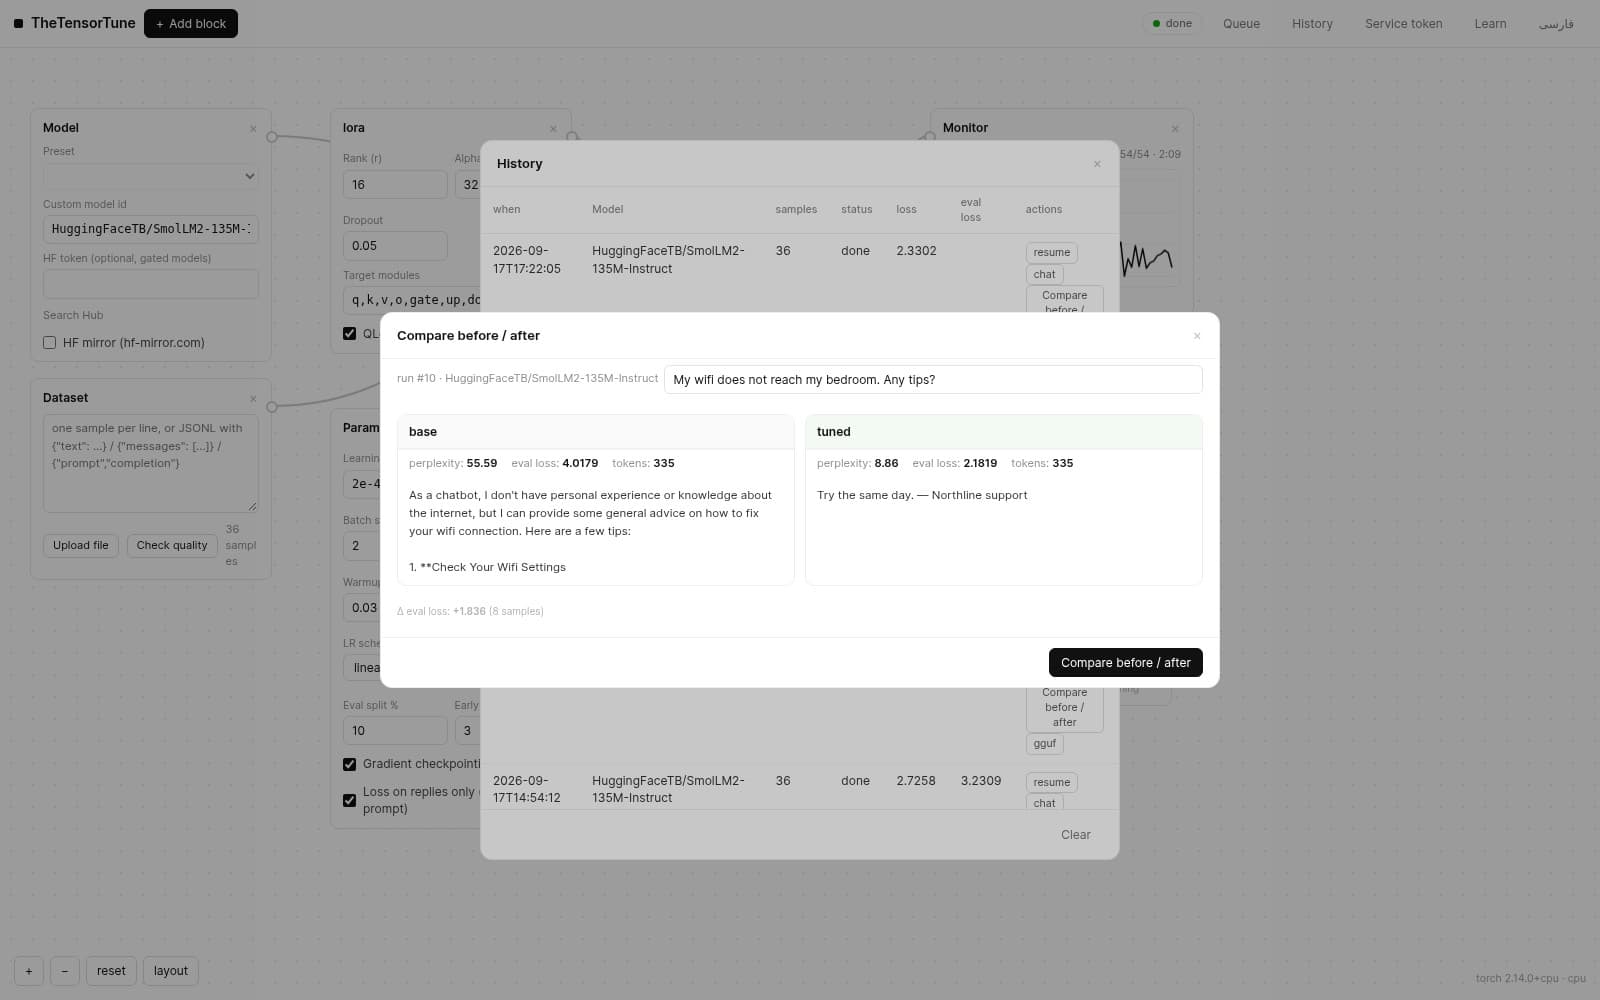
Tip: if the tuned ppl stays near the base one, either epochs were too few or the dataset does not match your goal.