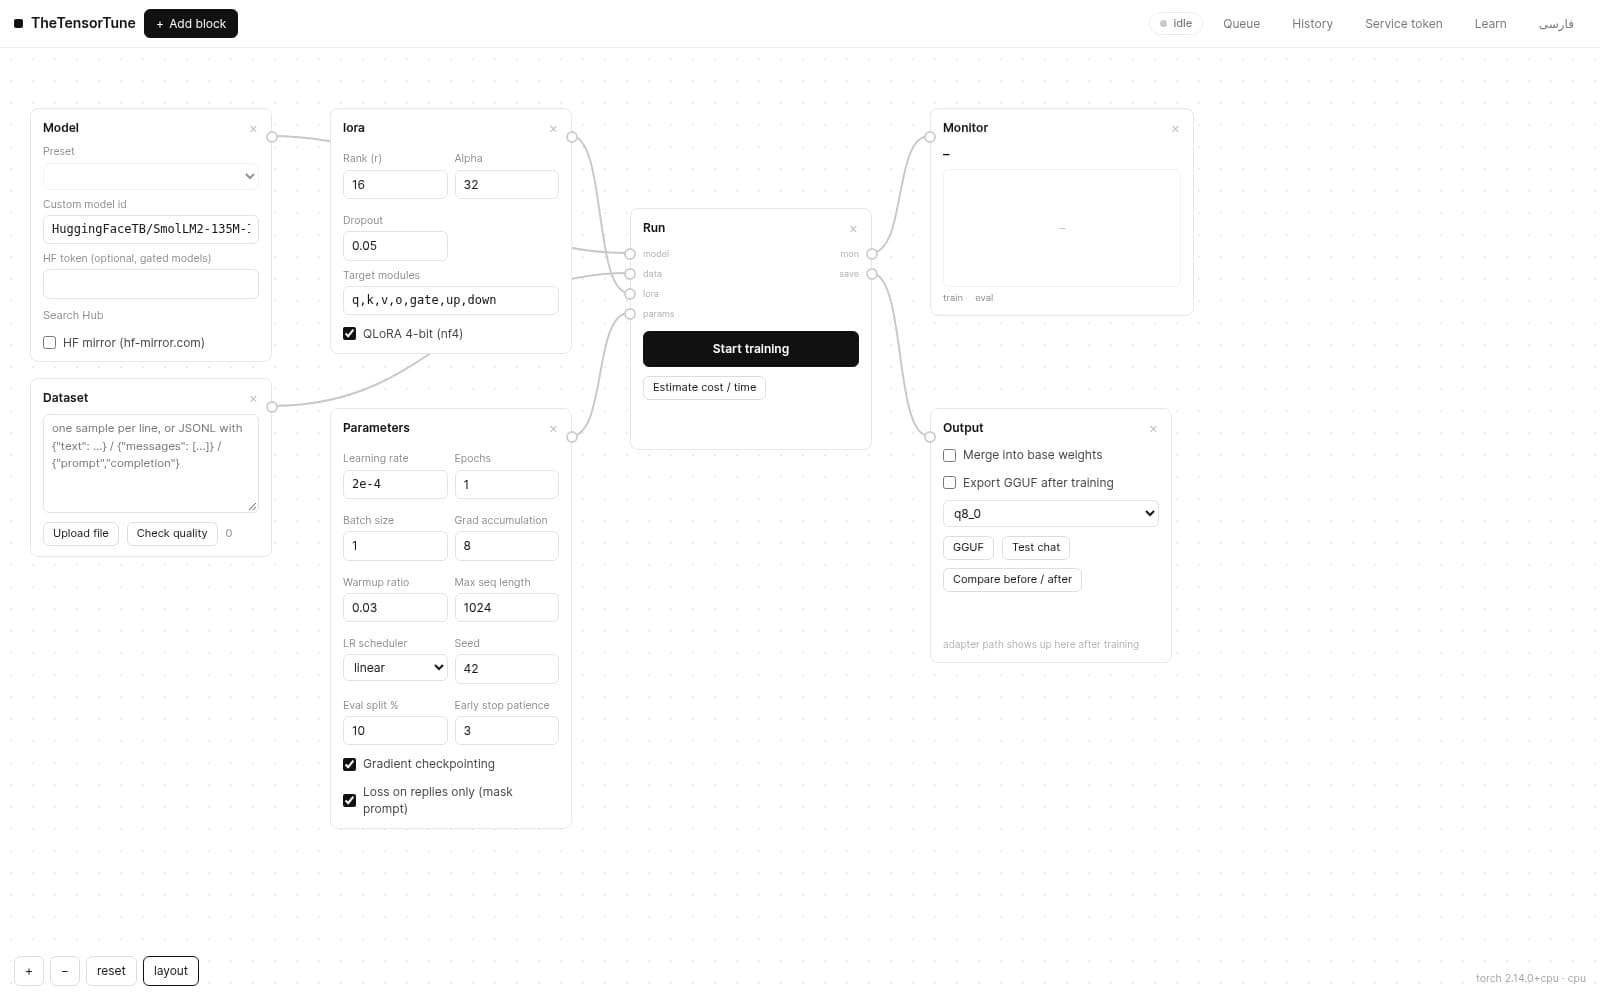
The Dataset block is the training input. Three formats are supported — upload a file or paste text directly:
{"messages": [{"role":"user",...},{"role":"assistant",...}]}— chat (recommended; only the assistant turn is trained){"prompt": "...", "completion": "..."}— prompt/completion{"text": "..."}or any plain line — free text
After uploading, Check quality gives a full report: sample count, format mix, duplicates, detected languages, a char/token length histogram and warnings. Persian and emoji content is fully supported.
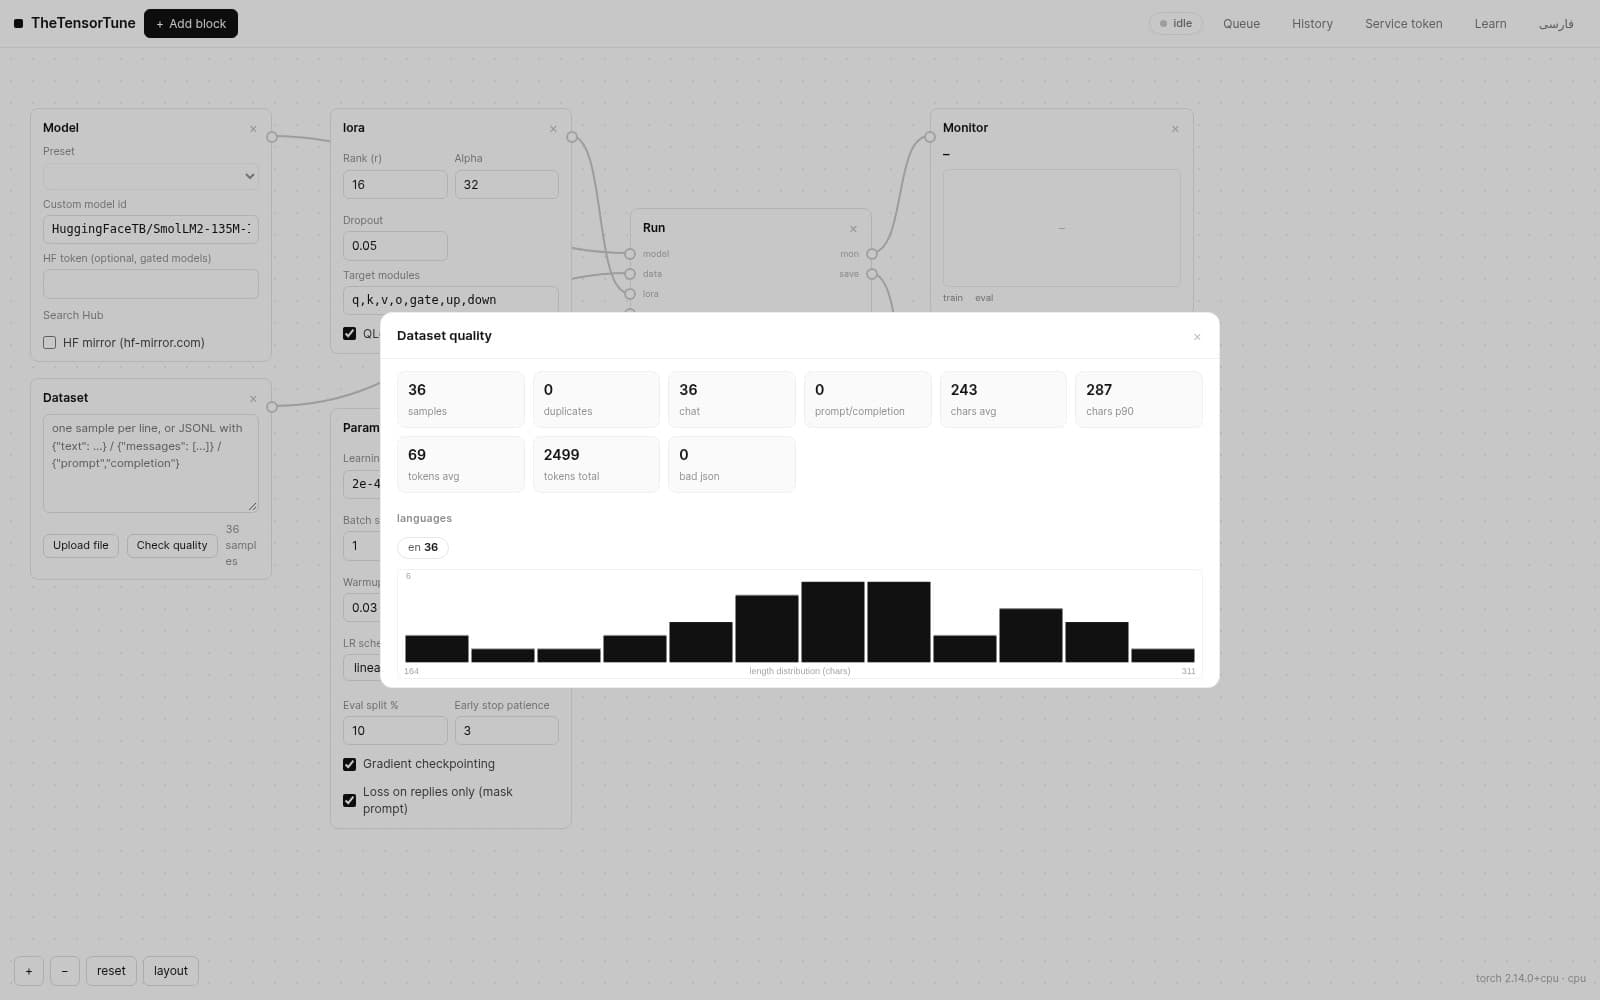
Tip: at least 2 samples are required; samples longer than ~6000 chars get a warning because maxlen truncates them. Deduplicate for a clean eval split.